Evaluating the price of a financial instrument implies most of the time to compute the expectation of a deterministic function of a random variable. This arises typically when the financial instrument payoff at maturity, noted , depends on the unknown realization of some underlying(s), represented by a random variable , assumed to follow a certain distribution.
The price is therefore, under a specific probability measure, , that is the expectation of .
In computational finance, this calculation must often be approximated by some numerical approach, as there isn’t any closed formula available for returning this result.
A frequently used method to compute this expectation is the Monte Carlo method.
To compute the expected value using Monte Carlo, one simulates the random variable many times, and take the average of all outcomes.
The Monte Carlo estimator is therefore given by the expression
where the are independent random draws of .
The more simulations are run, the closer the estimate gets to the true expected value.
The convergence of this estimator is proportional to the standard deviation:
Indeed using the central limit theorem, we have the confidence interval
where
- is the quantile of the normal distribution, and
- is an estimation of the standard deviation of .
As our goal is to increase numerical efficiency or accuracy of this calculation, we can either:
- Improve the convergence of our Monte Carlo estimator for a given number of simulations
- Achieve the same accuracy than the Standard Monte Carlo estimator but using less simulations
A usual trick to achieve this enhancement is the Importance Sampling (IS) method. It’s part of a broader family known as variance reduction techniques.
Its aim is to reduce the variance of a Monte Carlo estimator, thus accelerating its convergence speed.
As this method is very general from a theoretical standpoint, it’s widely used in various domains such as physic, biology, economy, …
Moreover, this method can also be implemented in a generic way, making it particularly suitable for wide use in LexiFi’s financial calculation platform.
Principle
The idea behind the importance sampling is to reduce the statistical uncertainty of Monte Carlo calculation by focusing on the most important region of the space from which the random samples are drawn. Such regions depend both on the random variable simulated, and the structure of the financial contract priced.
Importance Sampling means essentially that one is modifying the stochastic behavior of the Monte Carlo approach (by modifying how the realizations are drawn). To obtain nevertheless the same result for the expectation calculation, one has to adjust the random variable in a deterministic way.
It is the combination of a modification of the probability law of with a deterministic change of the outcome that allows the targeted enhancement of the Monte Carlo method: better statistical quality of the estimator while keeping it converging to the true expectation.
This method is indeed based on a modification of the sampling distribution to be more “adapted” to the problem (here the payoff of the financial contract) we are solving.
Example of distribution mapping:
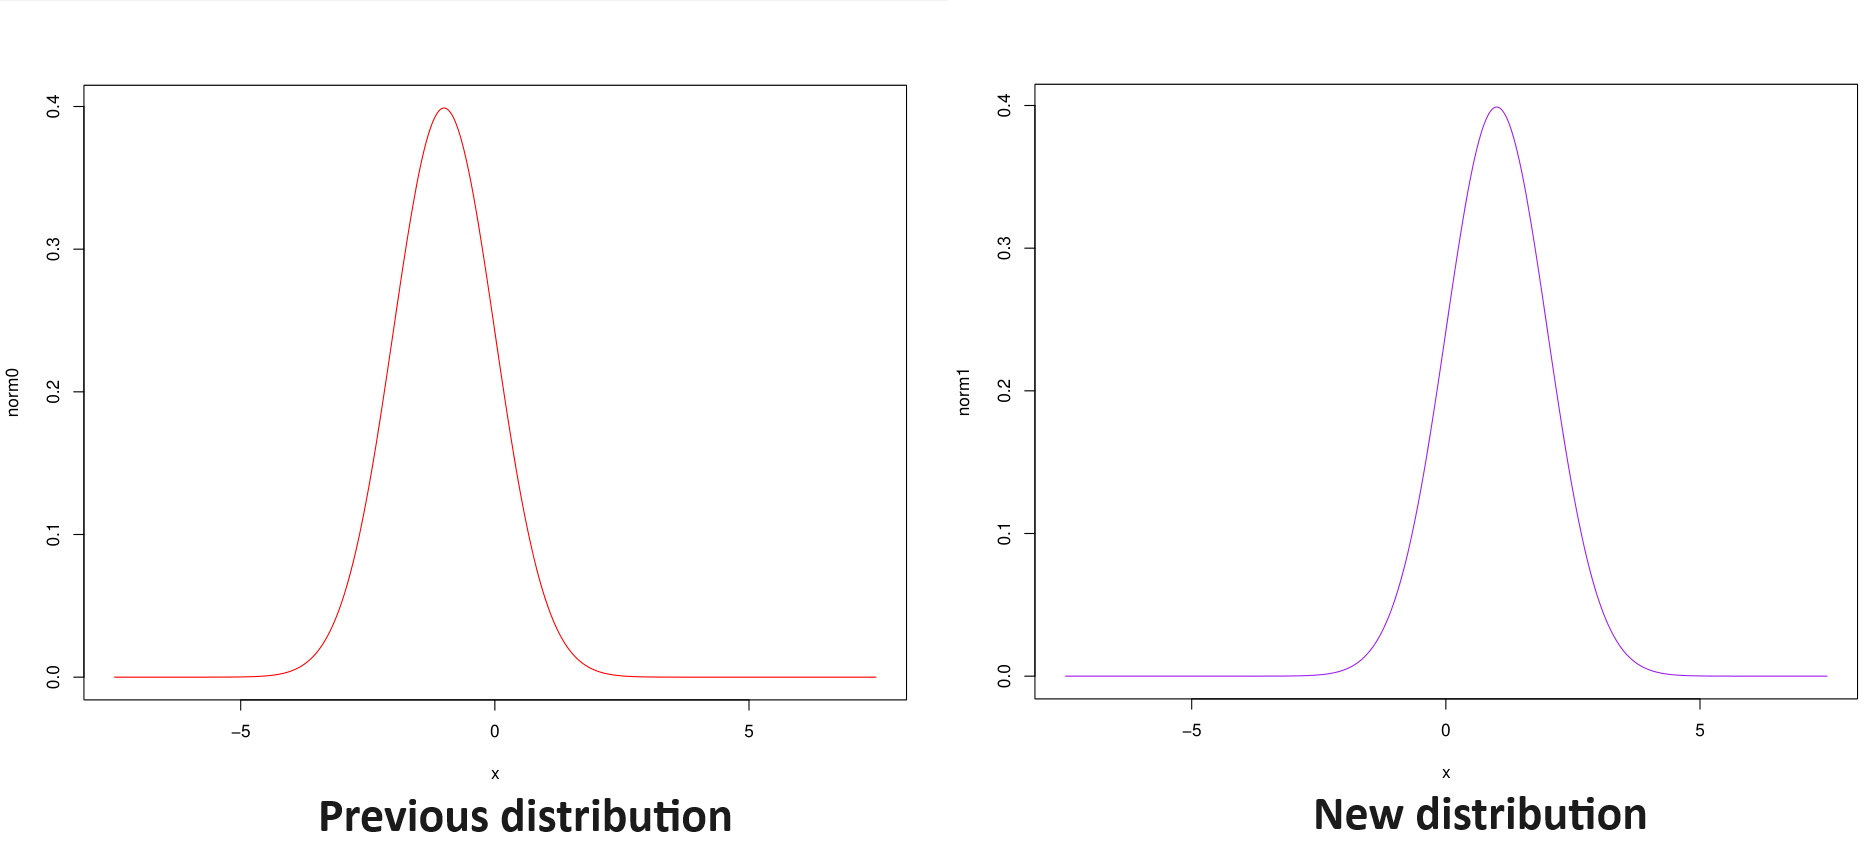
Let be the probability under which our Monte Carlo estimator is initially expressed.
Let be another probability, equivalent to .
The same expectation can be evaluated in two different ways:
| Under initial probability | Under new probability |
|---|---|
Note that previous equality works for any probability equivalent to , so doesn’t give us any hint about how to choose a good or even best one.
By reducing the set of admissible other probabilities, we will make the problem tractable and provide an efficient way to find in this set a “best” new probability.
Following notations will be used below:
- : number of simulations
- : number of factors
- : dimension of the time discretization
Monte Carlo (MC) estimator
Let’s apply this method to the Monte Carlo estimator.
Let’s note:
- a set of realization of under
- a set of realization of under
- a set of realization of under
We have
| MC estimator under initial probability | MC estimator under new probability |
|---|---|
Note that if
is a MC estimator of that converges faster than .
Our goal will therefore be to find a probability that minimizes .
Adapted to the pricing case
Let’s apply this generic variance reduction method to the specific case of financial contract valuation.
For reading purposes, we expose the pricing formula in the one dimension case.
Fundamental theorem of asset pricing (initial probability)
The price of a product at t is the actualized expected value of the future cash flows under the risk neutral probability knowing the information at t
Applying a probability change, the new pricing formula becomes:
Fundamental theorem of asset pricing (new probability)
The price of a product at t is the actualized expected value of the future cash flows multiplied by the probability change under the new probability measure knowing the information at t
Let us now apply this approach to the mostly encountered case in financial derivatives evaluation, when uncertainty is driven by Gaussian random variables.
Implemented case: Gaussian change of probability
MC estimators for prices usually uses factors that are Gaussian variables.
For most standard models, the source of randomness (Equities, Volatilities, Foreign exchange, Commodity, Inflation,…) are driven by a Brownian motion.
Let be a family of independent Gaussian variables. We want to estimate
The Monte Carlo estimator is then
where is the realization of .
Switching to a new probability, we get:
| MC estimator under initial probability | MC estimator under new probability |
|---|---|
where is the density of , and the density of .
Probability change, explanation (click to expand)
We want to change the mean and standard deviation of the Gaussian variables.
where
From Gaussian variables to Brownian processes
In practice, Gaussian variables are used to simulate Brownian increments. We’ll thus re-parameterize our estimator:
| MC estimator under initial probability | MC estimator under new probability |
|---|---|
Probability change, explanation (click to expand)
Let the number of time discretization. Let be the simulation dates for our brownians. Let be the Gaussian variables needed for the -th increment of the -th Brownian motion:
Where
We want to use a parameterization such that in the new probability, we change both the drift and the volatility of each Brownian motion, ie.
And in terms of :
And the corresponding density for the change of probability is
Remark on the probability change parameters dimension
We change the mean and the dispersion of each of the driving Brownian motions (risk factor).
We therefore express the new probability with parameters (independent of the dates).
If we take as an example the (one dimensional) Stochastic Local Volatility with Hull White one factor model (SLV/HW), we have one risk factor for:
- The underlying
- The volatility of the underlying
- The short rate
We have therefore 3 risk factors; for each of them, we may change the mean and the dispersion , so we have a total of 6 parameters to chose from.
Efficient optimization
Having developed the methodology and the setup in the financial application, our goal is now to find the optimal parameters. This problem is clearly an optimization one. We have to find the parameter such that the variance is minimal.
As expectations are equal for all possible probabilities, this problem is equivalent to the following one
Note that for each value of the optimization parameters, we need to evaluate:
- The payoff
- The probability change
To avoid the payoff evaluation, we evaluate previous expectation under the initial probability, allowing us to express our problem in following equivalent form
Using this expression, the algorithm will be:
- Simulate Gaussian variables
- Evaluate the time on the initial Gaussian variables
- For each iteration of the minimizer, evaluate times the probability change
Because this probability change is cheap to evaluate, this optimization procedure is highly efficient from a computation time point of view.
For a complete explanation of those expressions, please expand the following paragraph.
Calibration proof (click to expand)
The method presented here is mainly based on [GZL] and [LB]
If we want to minimize the variance, we need to find that minimize
We first note that
Thus, minimizing variance is equivalent to minimizing
This expectation can be approximated using a Monte Carlo estimator. Let be realizations of .
If we want to numerically minimize this empirical variance, we can:
- Simulate Gaussian variables
- For each iteration of the minimizer:
- Evaluate times on the scaled and shifted Gaussian variables
- Evaluate times
If the minimizer converges using steps, then is evaluated times, which can be really expensive, as is the composition of the evaluation of the payoff, to the computation of the trajectory on a model given uncorrelated Gaussian variables.
In order to reduce the number of required evaluation of , we note that
Using this approximation instead, the minimization will:
- Simulate Gaussian variables
- Evaluate time on the initial Gaussian variables
- For each iteration of the minimizer, evaluate times
We now have only evaluations of , instead of previously. Because the evaluation of is cheap (compared to the evaluation of ), the new algorithm is way faster.
Another major point is that when expanding the change of variable term, we are able to compute explicitly the partial derivative thanks to the drift and to the dispersion terms. This allows to implement a fast numerical optimization algorithm (we have access to the expression of the function and its Jacobian).
Applications
We focus on two ways of using the importance sampling approach in the context of expectation computation. Those points make also sense for most of the commonly used variance reduction techniques.
Application 1: Improve accuracy
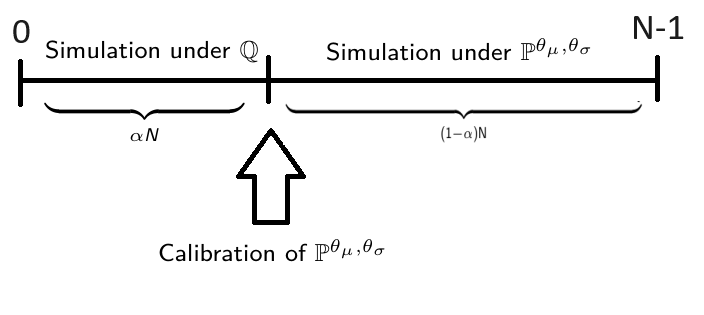
We suggest following algorithm to compute a Monte Carlo price estimator, using automatic Importance Sampling:
Let be the total number of Monte Carlo trajectories, and be the number of trajectories used to infer the optimal change of probability.
- simulate trajectories for the Gaussian variables:
- evaluate times the and store the evaluations:
- find the optimal by minimizing
- the remaining trajectories are computed using the optimal , and the final MC estimator is:
Following scheme summarizes this procedure:
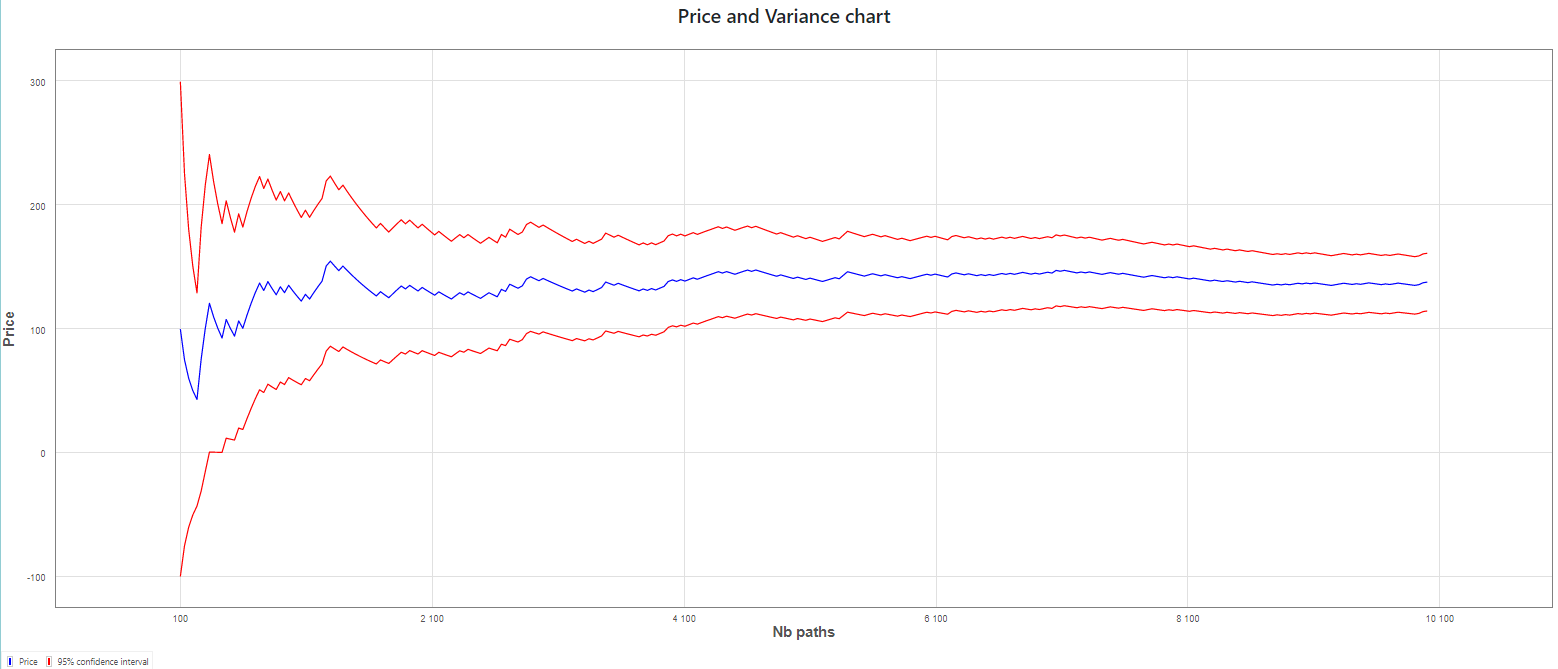
As an illustrative example, we apply this approach to the pricing of an autocall product:
- Here is the standard Monte Carlo estimator of the price with a 95% confidence interval
- For the same computation time, we are able to compute an estimator of the price using the importance sampling method with 9250 paths
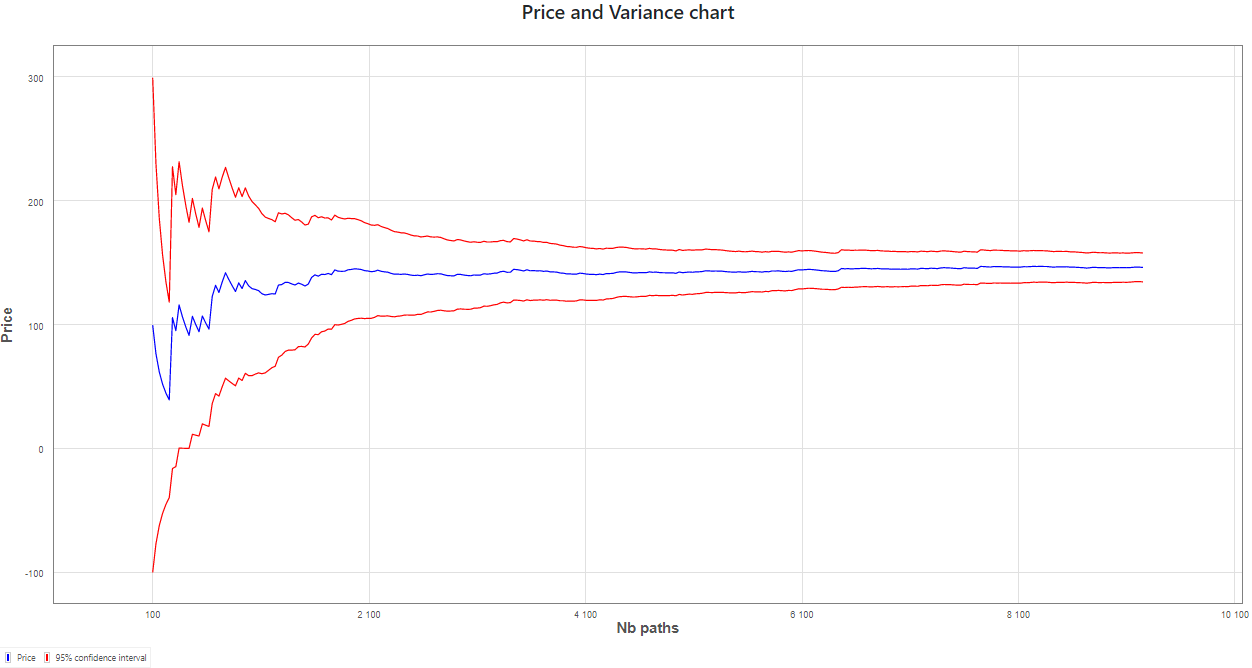
The confidence interval is, as expected, clearly reduced.
Empirical evidence:
| Method | Lower bound | Upper bound |
|---|---|---|
| Without IS | ||
| With IS |
The careful reader will also observe the increased “regularity” in the second chart, once Importance Sampling is activated, after optimization has been done, following initial simulations.
Application 2: Improve speed
The Importance Sampling will decrease the variance at a given number of trajectories, which will reduce the statistical error or the estimator (it will reduce the size of its confidence interval). We can also think of a mode that improve pricing speed, by decreasing the number of trajectories, without affecting the statistical error.
Here is a scheme that put in a nutshell this idea
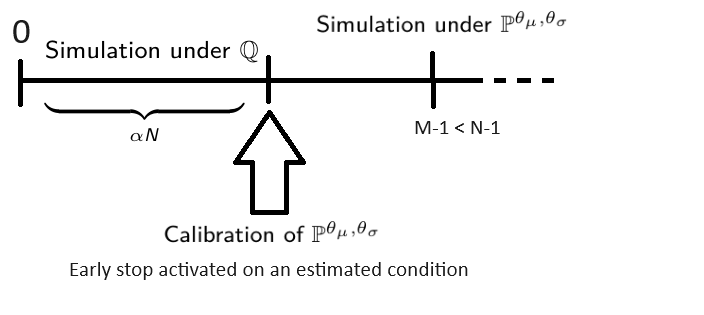
More details on speed mode (click to expand)
We recall that, by applying the central limit theorem, the MC estimator can be approximated by a Gaussian law, centered on the true expectation , with variance :
Thus, we have the confidence interval for the price, with probability :
Typically, for
Let be the random variable simulated with Importance Sampling applied. Theoretically, if we want to reach the same precision as without Importance Sampling, we want to stop at such that
To do that, can be estimated using the first simulations, that have been used for the inference of the optimal change of probability, and can be estimated for each trajectory, until the condition is empirically verified.
However, we note that this method is not perfect, because:
- We use an empirical estimation of the variance
- We use Sobol rng, that breaks usual statistical properties
In order to take these issues into account, we apply a ratio to our condition:
We calibrated the ratio on a realistic database of 5,000 autocalls, under Black-Scholes, Local Volatility and Heston models, with a reference price computed using 100,000 trajectories and Importance Sampling. We found that a ratio of allows to have statistically equivalent errors with 10,000 trajectories without Importance Sampling, and with Importance Sampling in Speedup mode. We also found that the risk of degradation when enabling Importance Sampling in speedup mode is the same as when disabling this mode (quantified by the distribution of the absolute error difference between IS and No IS). As a matter of fact, the price is sometimes improved, sometimes degraded (about 50% in each case). For speedup analyses please refers to Technical documentation. In this study, the total pricing time decreases by in Speedup Mode, compared to No Importance Sampling.
In this example we use the same pricing with a standard Monte Carlo method as in previous example. We then compare it with a Monte Carlo method using the Importance Sampling for achieving same accuracy.
-
Monte Carlo estimator using 10000 paths
-
Monte Carlo estimator with Importance Sampling using 3200 paths
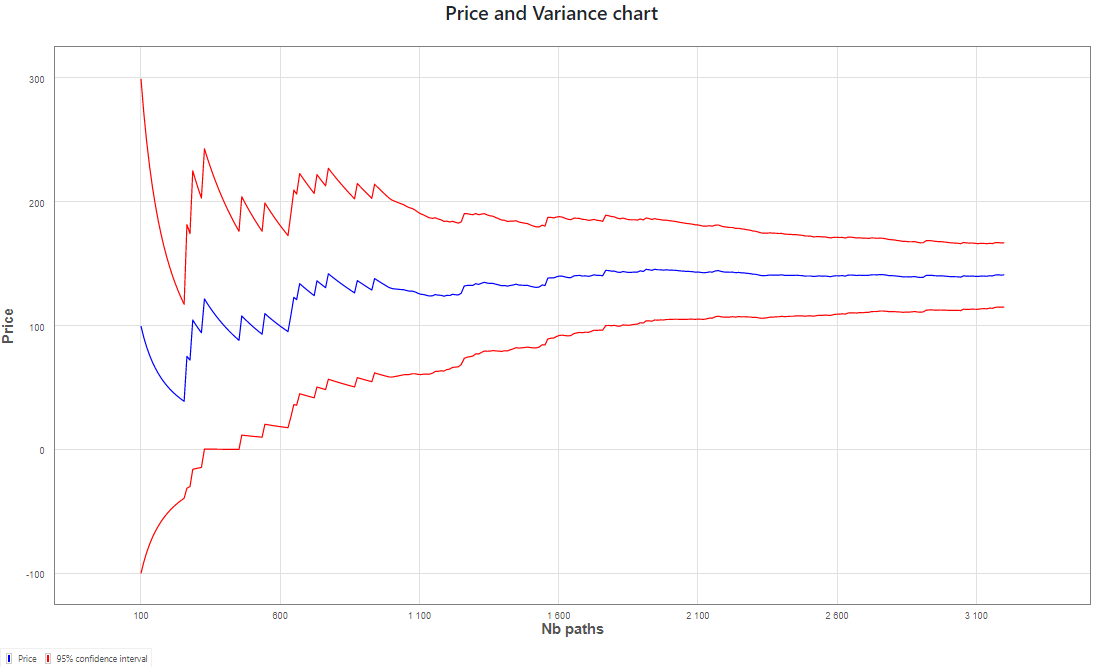
In this particular example, we achieve the same accuracy with only a third of initial number of paths. As initial optimization takes some computational time, we nevertheless achieve a computation that is 2.27 times faster.
Conclusion
We focus our attention on a variance reduction technique known as Importance Sampling and explore its application in the pricing field. A major point is that the sources of randomness come from the uncertainty of the future value of underlying assets, mostly modeled using Brownian motion.
One of the major issues is the choice of “optimal parameters” for the change of probability. Based on a theoretical study and a careful numerical implementation, we expose an efficient algorithm that involves a small number of payoff evaluation. Thanks to the analytic expression of the partial derivatives, the optimization itself converges very fast.
Once these parameters are determined, we apply this method to two modifications of the standard Monte Carlo procedure: to enhance accuracy or improve speed.
LexiFi’s highly integrated pricing engine allows for an efficient implementation of this approach, shared by all MC models available in LexiFi’s solution.
Because this approach is organized in a highly generic manner, it smoothly interacts with all other LexiFi’s Monte Carlo features including adjusters, Romberg Richardson method, efficient numerical schemes, American feature, … and all the applications of LexiFi solution.
References
[GZL] Guiding Gu Qiang Zhao, Guo Liu. Variance Reduction Techniques of Importance Sampling Monte Carlo Methods for Pricing Options. Journal of Mathematical Finance, January 2013, www.researchgate.net
[LexiFi] LexiFi model documentation, Importance Sampling, www.lexifi.com
[LB] Jérôme Lelong Benjamin Jourdain. Robust adaptive importance sampling for normal random vectors. The Annals of Applied Probability, November 2008, //arxiv.org